Week 1 · 22 February
Lecture: What a Language Model Learns
Guided session: Project 1 Launch and Data Validation
This week: Validate the story split and define the training target.
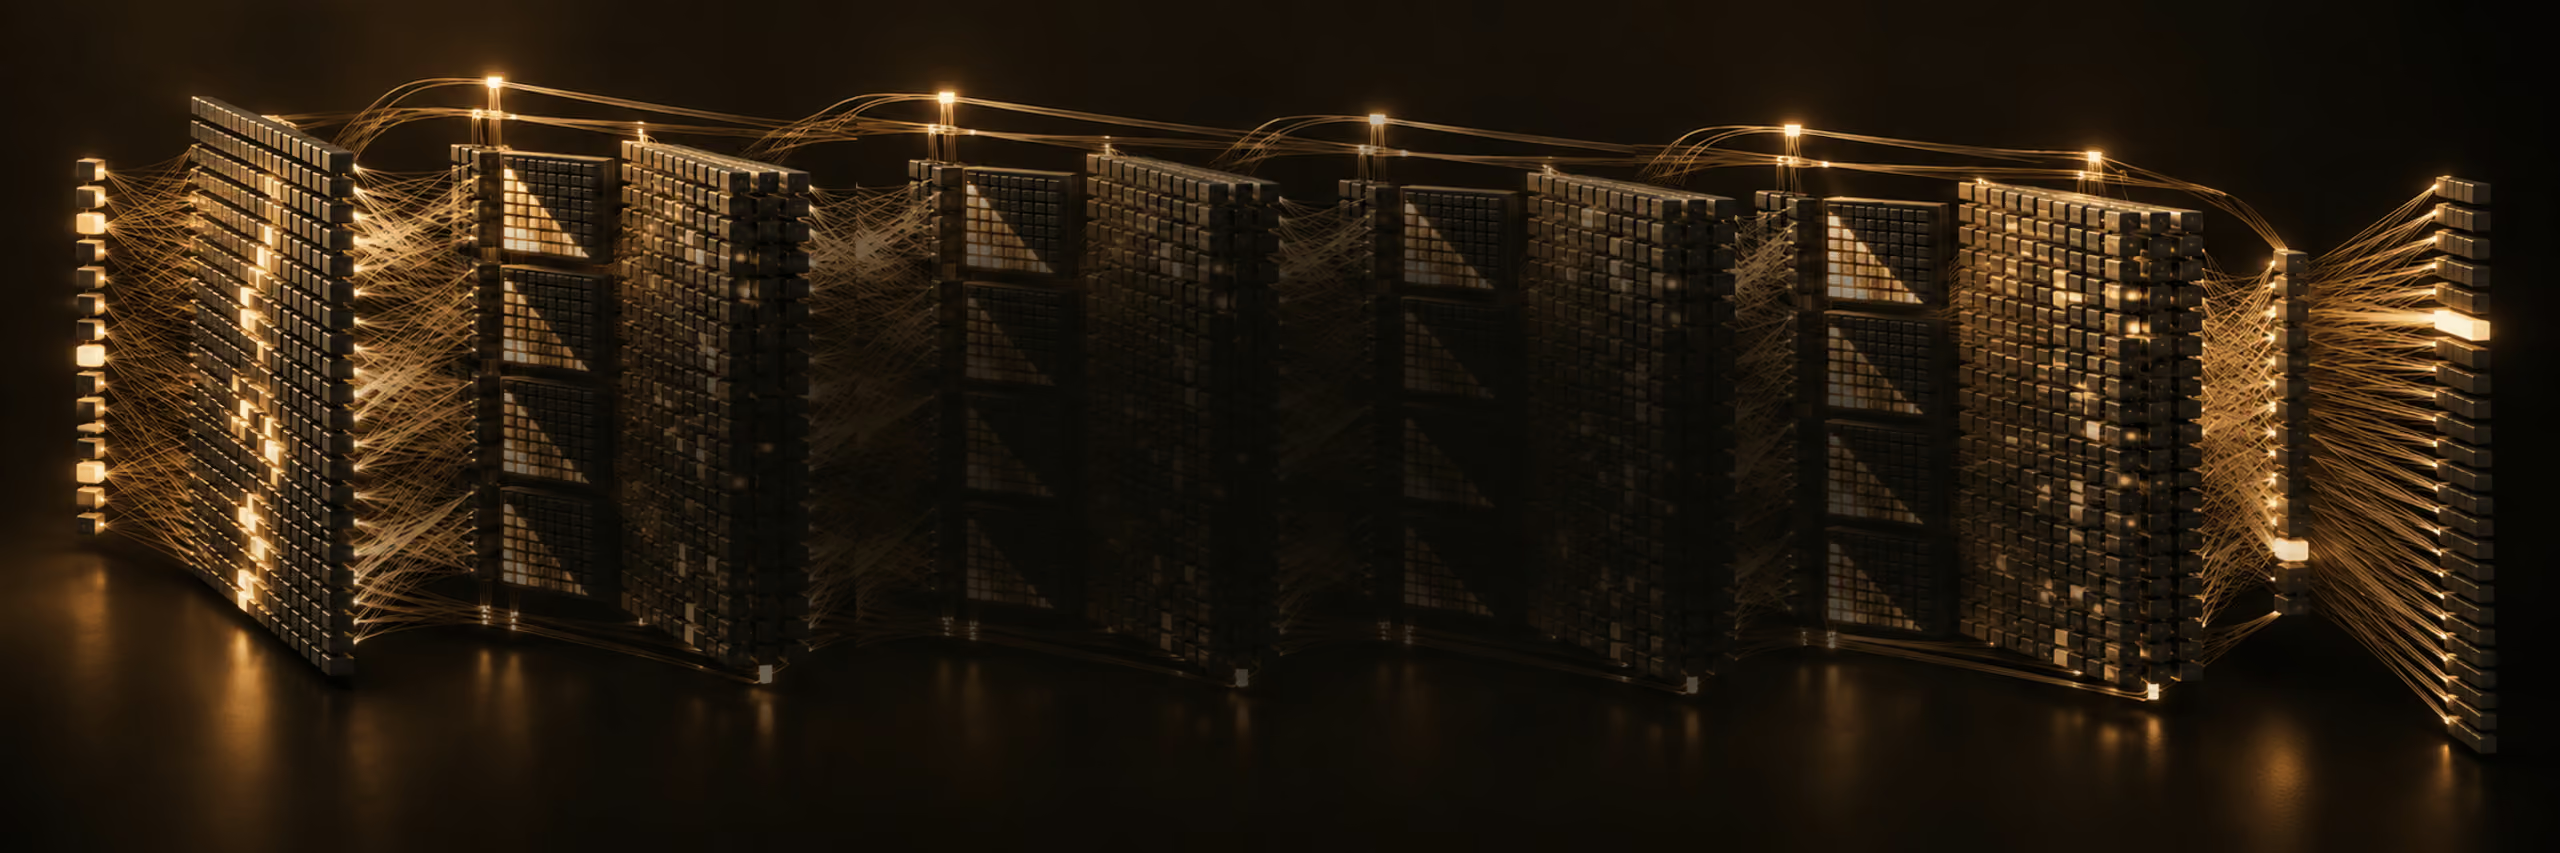
Hands-on frontier practice to perceive language model training & fine tuning: It is a Budgeted Engineering Task.
SLOP4225 · Semester 1, 2027
Most language-model courses begin after the expensive decisions have already been made. This course begins before the first training token. You will choose how to spend a limited model and compute budget, build a narrative language model from scratch, reshape its behaviour through post-training, and adapt it for one bounded specialist task.
The objective is not to imitate a frontier model at miniature scale. It is to learn which claims survive contact with limited parameters, limited data, limited compute, and evidence you must be able to defend.
Work through three connected projects that follow the life of a language model. You will pre-train a narrative model from scratch, reshape its behaviour through post-training, and adapt a permitted checkpoint for one specialist capability. At every stage, you will make choices about the model, data, training budget, and evaluation—and use evidence to decide whether those choices worked.
This course is for senior undergraduate and postgraduate students who have ever wondered what actually happens inside the training run behind a language model, and want to stop taking that on faith. It suits anyone who enjoys turning a vague claim about scale, data, or alignment into an experiment they can run and defend with evidence, and who would rather make one deliberate training decision than run a large search and hope.
By the end, you will have trained a real language model of your own from scratch, reshaped its behaviour on purpose, and specialised it for a task you chose — and be able to explain, with evidence, why each of those choices worked or didn't.
You should have completed introductory machine learning and be comfortable with basic Python, linear algebra, and probability. Prior experience with PyTorch, GPUs, or training a language model is not required — the supported sessions and starter repositories introduce the working pipeline before you depend on it in an assessment.
Pre-train a decoder-only Transformer on a supplied narrative corpus. Decide how model capacity, tokenization, data, optimisation, and runtime fit together under a 32M-parameter design target.
Project 1: Build a Narrative Base Model · Weeks 1–4 · 20% · due Sunday 21 March 2027, 23:59 AET
Start from a narrative checkpoint and give the model a recognisable voice. Compare continued pre-training, supervised instruction tuning, preference-based methods, or a justified combination without hiding regressions behind one improved metric.
Project 2: Give the Model a Voice · Weeks 5–8 · 50% · due Sunday 25 April 2027, 23:59 AET
Adapt a permitted checkpoint for one measurable function. Choose a bounded narrative capability or arithmetic reasoning, test generalisation, and determine what the intervention changed as well as what it damaged.
Project 3: Build a Specialist · Weeks 9–12 · 30% · due Sunday 23 May 2027, 23:59 AET
Start with Week 1View the three projects
Each week connects one lecture, one practical or support session, and the next decision in the current project. Open either activity directly and use this week as the minimum project checkpoint to reach before moving on.
Lecture: What a Language Model Learns
Guided session: Project 1 Launch and Data Validation
This week: Validate the story split and define the training target.
Lecture: Inside a Decoder-Only Transformer
Formal lab: Lab 1 — Spend a 32M Parameter Budget
This week: Freeze a feasible baseline architecture.
Lecture: Scale, Data, and Optimisation Under Fixed Compute
Drop-in clinic: Project 1 Pilot Clinic
This week: Freeze the principal run plan.
Lecture: Evaluate, Decode, and Package a Base Model
Guided session: Project 1 Evaluation and Packaging
This week: Submit Project 1 by 21 March, 23:59 AET.
Lecture: From a Base Model to a Target Behaviour
Guided session: Project 2 Target and Baseline Planning
This week: Define the target voice and unchanged-model baseline.
Lecture: Supervised Fine-Tuning and Data That Teaches Behaviour
Formal lab: Lab 2 — Build and Inspect a Post-Training Batch
This week: Produce a masking check and viable pilot.
Mid-semester break, Monday 5–Sunday 11 April 2027 — no teaching. Preserve logs and checkpoints outside the runtime.
Lecture: Learning from Preferences Without Hiding the Cost
Drop-in clinic: Project 2 Behaviour Clinic
This week: Freeze the evaluation comparison.
Lecture: Did the Behaviour Change, and What Regressed?
Guided session: Project 2 Blind Evaluation and Packaging
This week: Submit Project 2 by 25 April, 23:59 AET.
Lecture: Reasoning as Generated and Verifiable Behaviour
Guided session: Project 3 Task Contract and Baseline
This week: Choose a track, define one capability, and establish the baseline.
Lecture: Train a Specialist That Can Be Tested
Formal lab: Lab 3 — Train and Verify a Specialist
This week: Produce one loadable pilot and a valid task metric.
Lecture: Generalisation, Supervision, and One Honest Ablation
Drop-in clinic: Project 3 Generalisation Clinic
This week: Freeze the candidate checkpoint and bounded claim.
Lecture: Audit the Training System
Guided session: Project 3 Fresh-Load Audit and Submission
This week: Submit Project 3 by 23 May, 23:59 AET.
By the end of the course, you should be able to:
Every project has a learned-parameter boundary and two cumulative compute ceilings. Pilots, ablations, failed training runs, and final runs all count. The constraint is part of the subject: strong work chooses informative experiments, preserves evidence, and stops when another run would not answer a useful question.
The course provides working starter repositories, versioned data, Colab notebooks, evaluation packs, and course-managed fallback compute. Prior experience training an LLM or using a GPU is not required; introductory machine learning, basic Python, and willingness to inspect PyTorch code are expected.
| Teaching block | Project | Weight | Deadline |
|---|---|---|---|
| Weeks 1–4 · Pre-training | Project 1 — Build a Narrative Base Model | 20% | Sunday 21 March 2027, 23:59 AET |
| Weeks 5–8 · Post-training | Project 2 — Give the Model a Voice | 50% | Sunday 25 April 2027, 23:59 AET |
| Weeks 9–12 · Specialisation | Project 3 — Build a Specialist | 30% | Sunday 23 May 2027, 23:59 AET |
| Total | 100% |
Three roles carry deliberately different responsibilities: the convenor for course concepts and assessment design, a teaching fellow for implementation questions, and a compute steward for platform and budget issues. Open a card for a teacher's full profile and contact details.
Course Convenor and Lecturer
Yiwei teaches language-model training at the intersection of machine learning, empirical evaluation, and resource-aware systems.
Teaching Fellow and Technical Tutor
Maya runs the practical labs and model clinics, with a focus on PyTorch, dataset pipelines, training diagnostics, checkpoint loading, and reproducible evaluation.
Compute Steward
Eli protects the fairness and operability of the constrained-training environment, from compute accounting to platform incidents.
Training begins with the target, not the training loop. In Week 1, you will turn story text into token targets and make the first decision that affects every later result.