Week 8: Continuity
Holding a character and a location steady across shots with a reference library and a model sheet — LoRA and DreamBooth against reference adapters, the scene master plate, and the audit that checks it held.
26 April 2027
- Monday lecture: Continuity
- Wednesday Dailies: The Continuity Pass
- Friday due: A8 (3%)
A generated character has no memory of its own face between shots; whatever consistency a scene has comes entirely from what gets fed back into the generator on your own graph, not from anything the model remembers on its own. This week turns that feeding-back into a system: a reference library built once, a model sheet that documents what’s in it, and an audit that checks every new shot against it rather than trusting a general impression.
Two ways to lock identity#
There are two genuinely different ways to make a generator produce the same face repeatedly. Reference adapters — the kind Phase 2 already used to carry identity from an image into a new generation — need no training and work the moment a reference image exists, but they hold identity loosely enough that drift is still possible under enough motion or style pressure. LoRA and DreamBooth work the opposite way, and they are not two names for one method. Both want a training pass on a few images of the subject before the first shot rather than a reference handed over at generation time, and both hold a subject harder than any single reference image does. Where they part is what they train. DreamBooth trains the model itself — its method is to “fine-tune all layers of the model” — so what comes out is a whole checkpoint, at a whole checkpoint’s training cost and disk footprint. LoRA leaves the pretrained model where it is: it “freezes the pre-trained model weights and injects trainable rank decomposition matrices into each layer”, so what comes out is a small file that loads on top of a checkpoint you already have.
Source: DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation — https://arxiv.org/abs/2208.12242
Source: LoRA: Low-Rank Adaptation of Large Language Models — https://arxiv.org/abs/2106.09685
The model sheet#
A model sheet is the document a reference library becomes once it’s organised for someone else to use: a face reference, a full costume reference, and a short list of props or details a viewer would notice if they changed. Building the sheet once, before the season’s first real shot, is what turns “I remember what the costume looks like” into something a second person — or a second week of production — can check against without asking.
The scene master plate#
A scene that runs several shots in the same location needs one more reference beyond the character: a master plate of the location itself, locked the same way a face is locked, so a background detail doesn’t drift between two shots that are supposed to be seconds apart in the same room. Without a master plate, a location regenerated fresh for each shot will look plausible in isolation and inconsistent the moment two shots sit next to each other in an edit.
The audit#
Checking continuity means comparing every new shot against the model sheet and the master plate item by item — face, costume, key props, location — not watching a rough cut and trusting that it felt right. An audit produces a pass or fail per item, not a single verdict for the whole shot, because a shot can pass on the face and fail on a prop in the background at the same time.
t1Face reference against the take from 1 reference: face
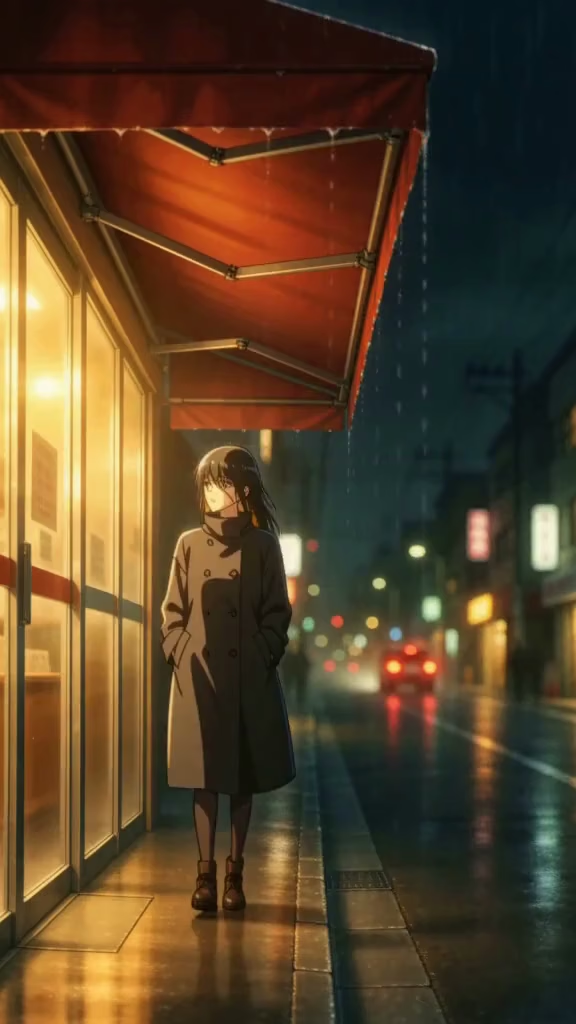
One face reference across a two-shot cut: watch the coat and the street change at 00:07.
t4Scene master plate against the take from 5 references: + scene
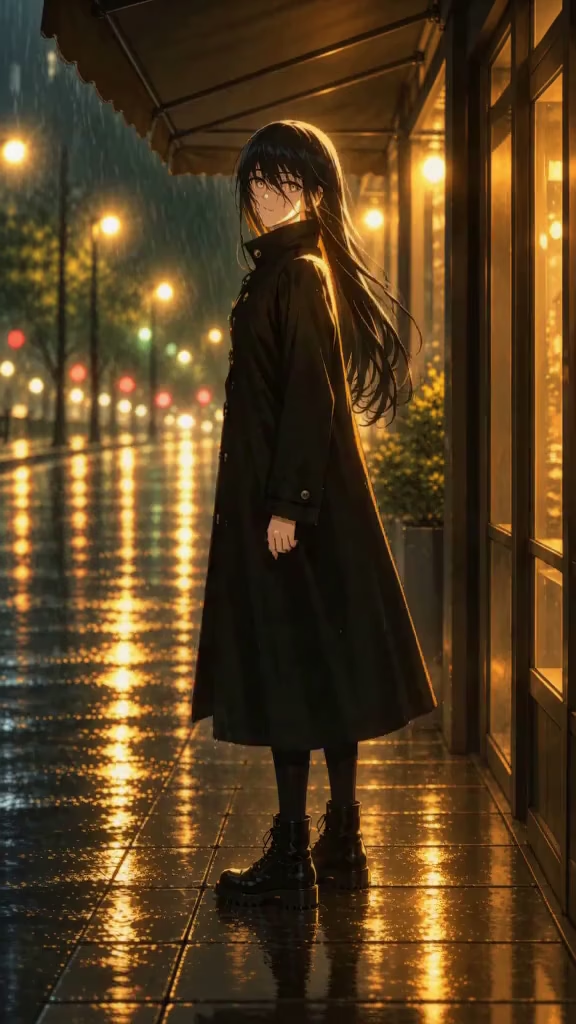
With the street pinned too, both shots should look like the same place at the same hour.
The ladder#
The ladder this week builds one two-shot scene, climbing through how complete the reference set behind it is. The lowest tier uses a single face crop as the only reference. The next tier adds one full-length reference alongside the face, which is what fixes the coat length and the boots across the cut. The next tier doubles that set with the same character dry, half-length and full-length, so both costume states the scene passes through have a reference behind them. The top tier keeps the full set and adds a scene master plate for the location the two shots share.
t11 reference: face
One face reference across a two-shot cut: watch the coat and the street change at 00:07.
t22 references: face + full body
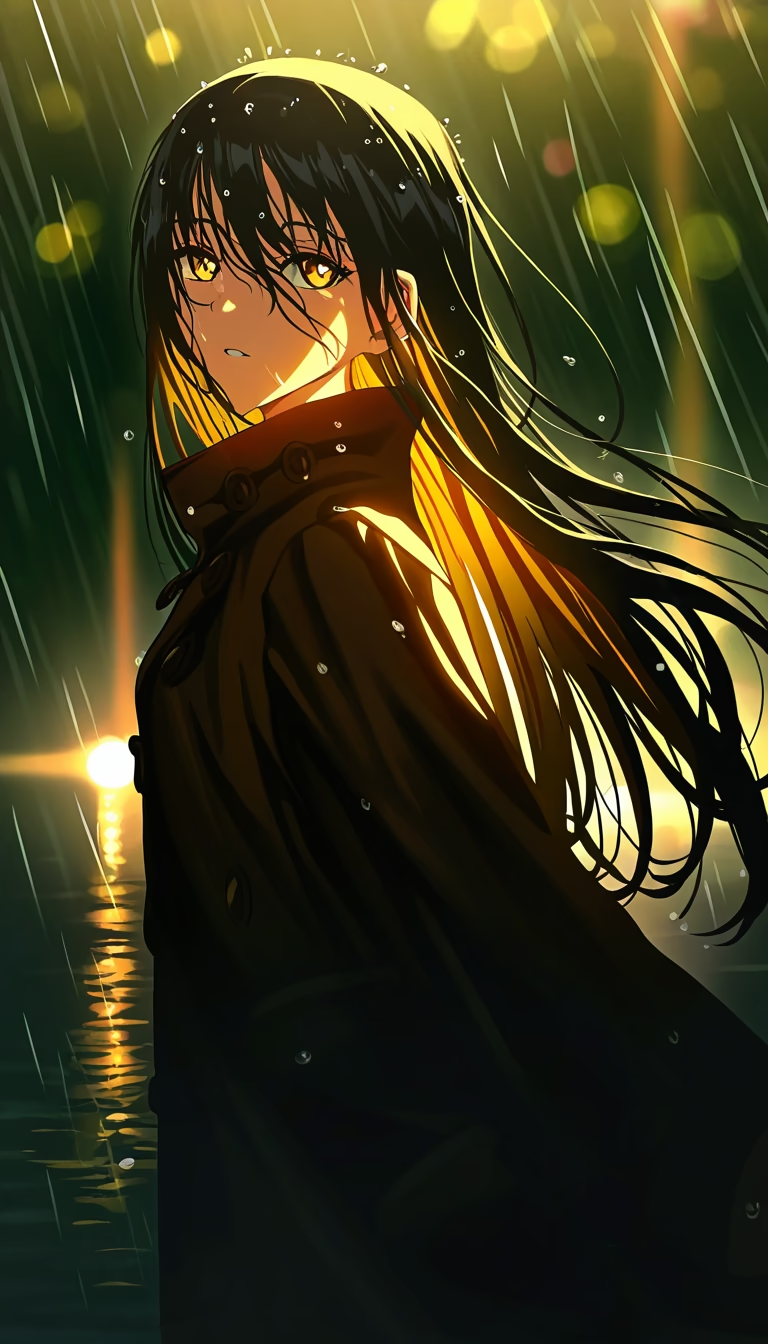
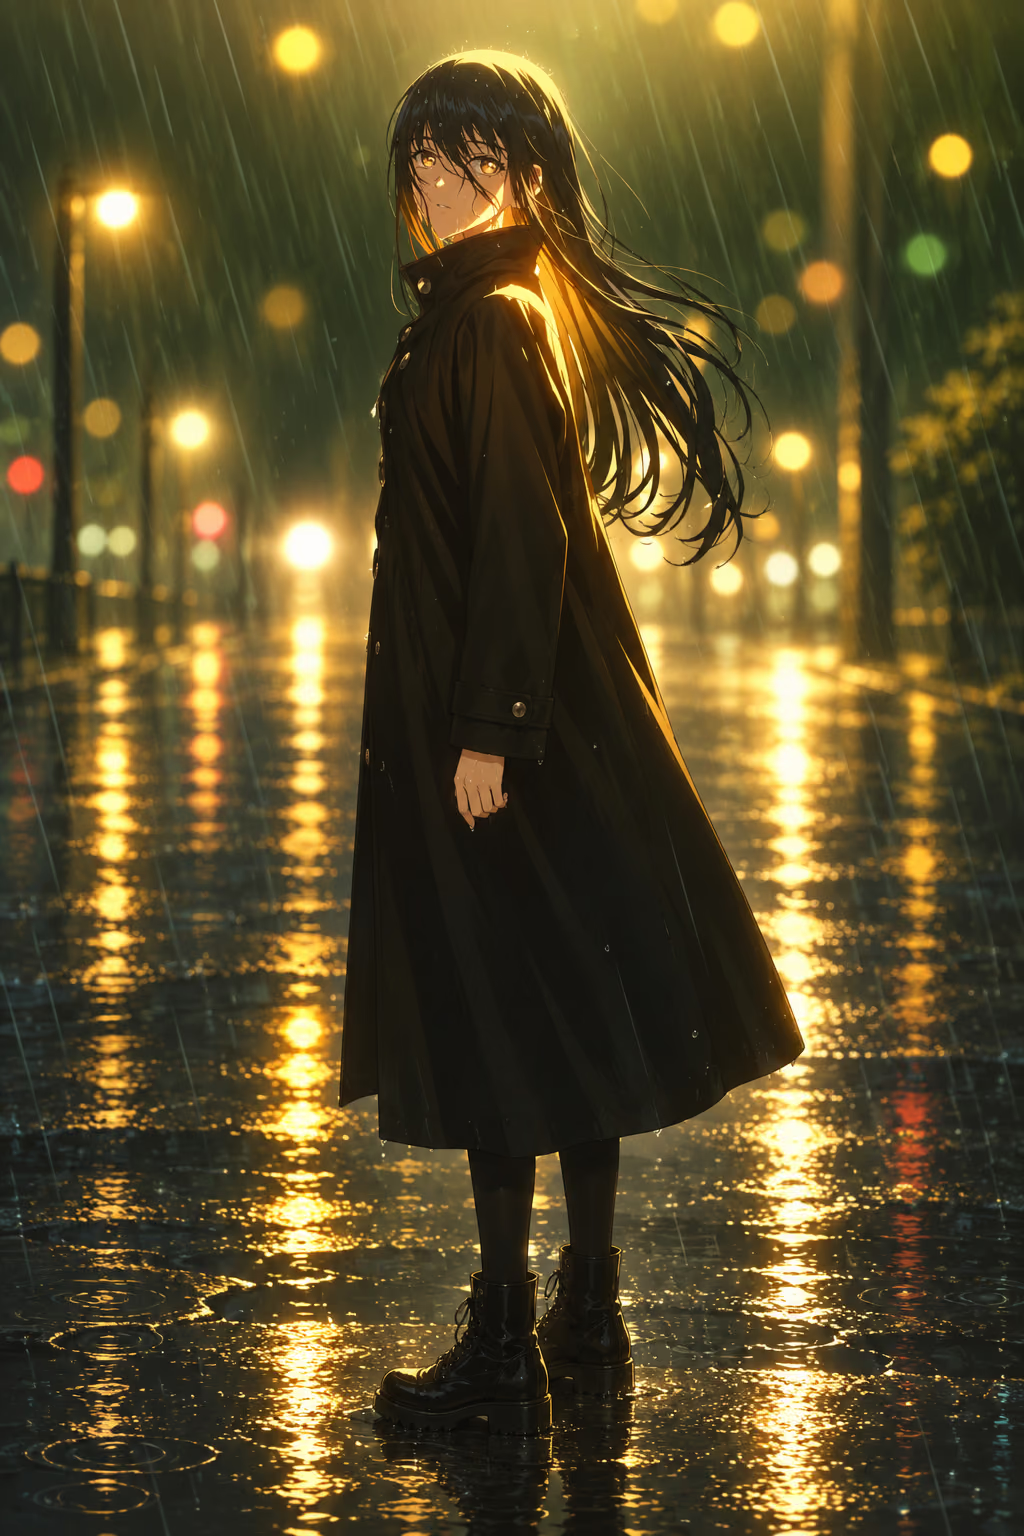
Adding the full-length picture fixes the coat length and the boots across the cut.
t34 references: + dry state
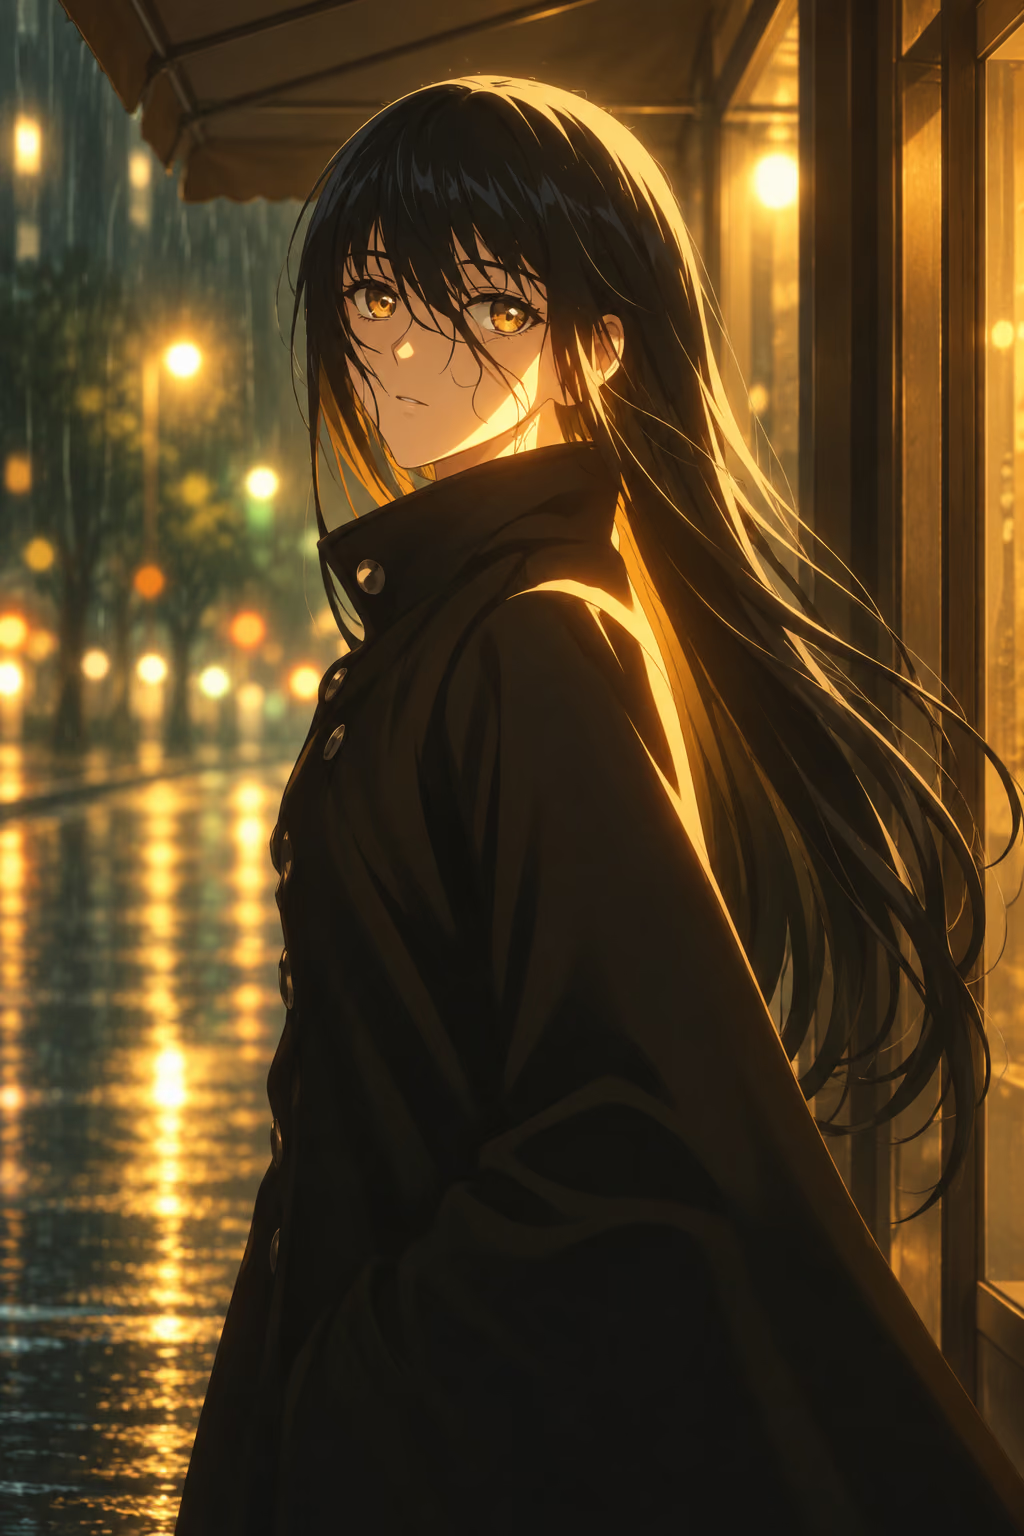
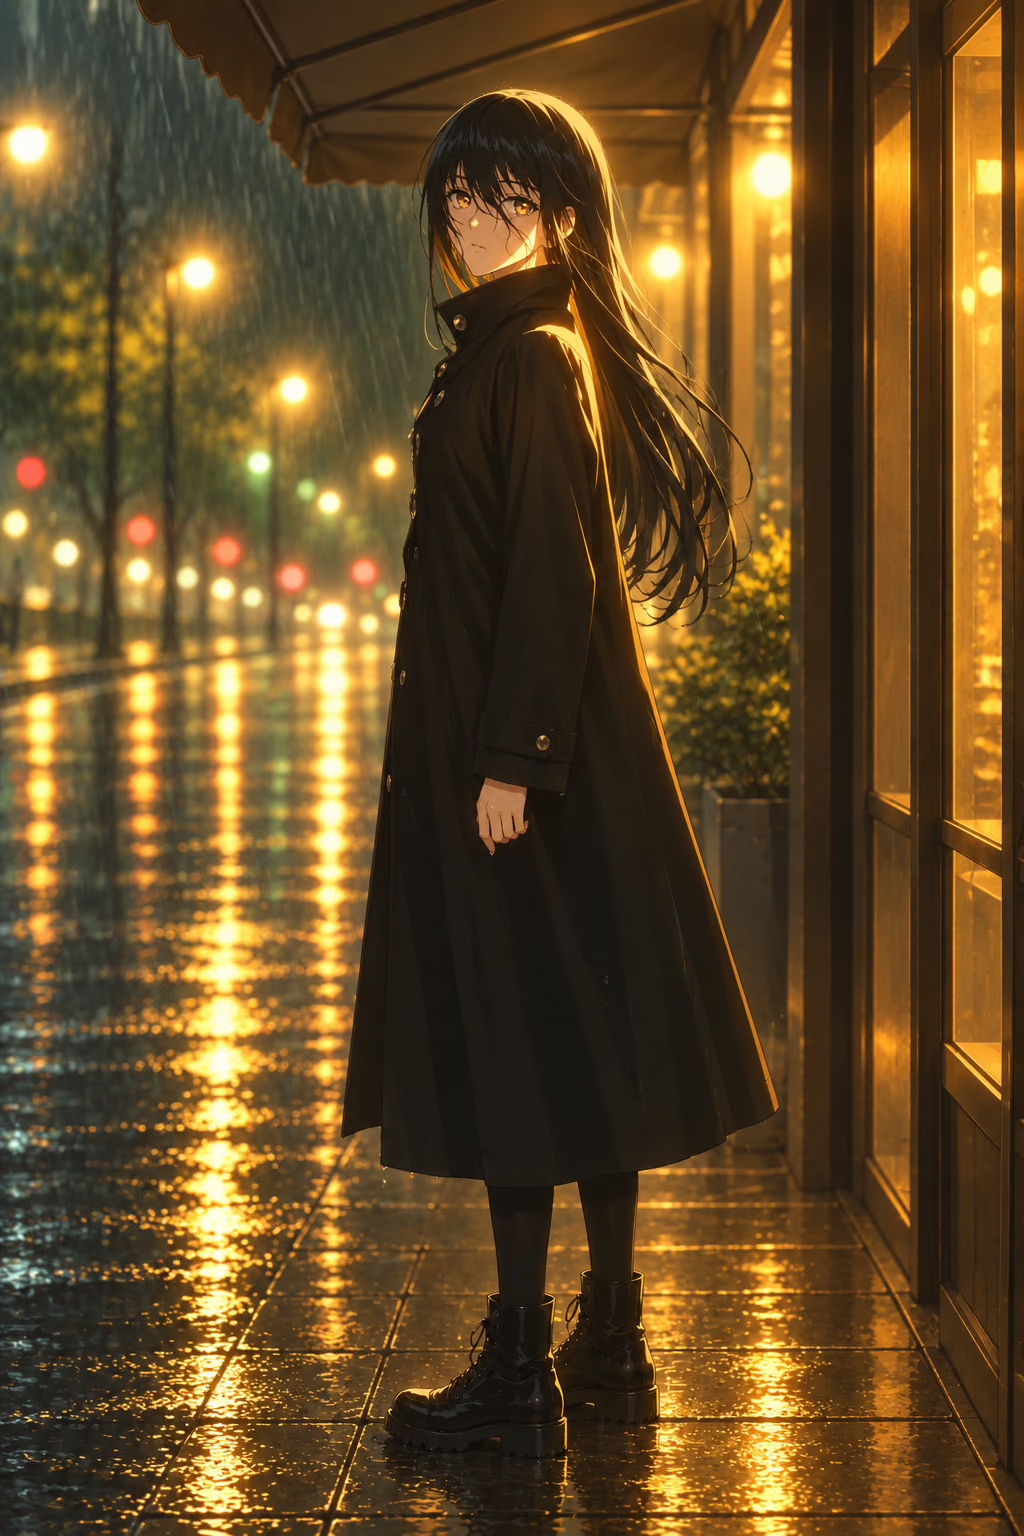
The dry pair is what makes Shot 1 read as dry - check the hair before she steps out.
t45 references: + scene
With the street pinned too, both shots should look like the same place at the same hour.
Before class#
Gather whatever reference images already exist for one character — even just a single face crop — to use as the starting point for this week’s ladder.
This week’s exercise#
Build all four ladder tiers of reference material, then generate the same two-shot scene against each tier and audit both shots item by item. Bring the four reference sets, the resulting shots, and the audit notes to Wednesday’s Dailies.
Reading#
LoRA: Low-Rank Adaptation of Large Language Models
Hu et al.2021
freezes the pre-trained model weights and injects trainable rank decomposition matrices into each layer
DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation
Ruiz et al.2022
Given only a few (typically 3-5) casually captured images of a specific subject
VACE: All-in-One Video Creation and Editing
Jiang et al.2025
reference-to-video generation, video-to-video editing, and masked video-to-video editing
Phantom: Subject-consistent video generation via cross-modal alignment
Liu et al.2025
extracts subject elements from reference images and generates subject-consistent videos following textual instructions
MiniMaxAI2026
Up to 9 reference images, 3 reference videos
Teaching team
- Vera Lin — Convener