Continuity
Week 8 · SLOP8760
Phase 3 of 4 · Holding It Together
This week adds
Continuity as a system: a reference library built once, a model sheet that documents it, and an audit that checks every new shot against both.
Two ways to lock identity
10,000xfewer trainable parameters than GPT-3 175B fine-tuned with Adam
Reference adapters need no training and hold loosely. LoRA trains first and holds harder: it freezes the pretrained weights and injects trainable rank decomposition matrices into each layer instead. The ratio is that paper’s own language-model measurement, not a figure for a diffusion checkpoint.
Source: LoRA: Low-Rank Adaptation of Large Language Models — https://arxiv.org/abs/2106.09685
Given only a few (typically 3-5) casually captured images of a specific subject
Ruiz et al., DreamBooth, 2022
Source: DreamBooth — https://arxiv.org/abs/2208.12242
The reference set is the whole system
The top tier hands the model five references: the face, the full body, two dry states, and the street itself as a subject of its own. H3’s reference task takes up to nine images, three clips, and twelve files in total.
Source: MiniMax-H3 model card, Tasks — https://huggingface.co/MiniMaxAI/MiniMax-H3
The model sheet, then the audit
Face, costume, props, location — a verdict per item, not one verdict for the shot. A shot can pass on the face and fail on a prop in the background at the same time.
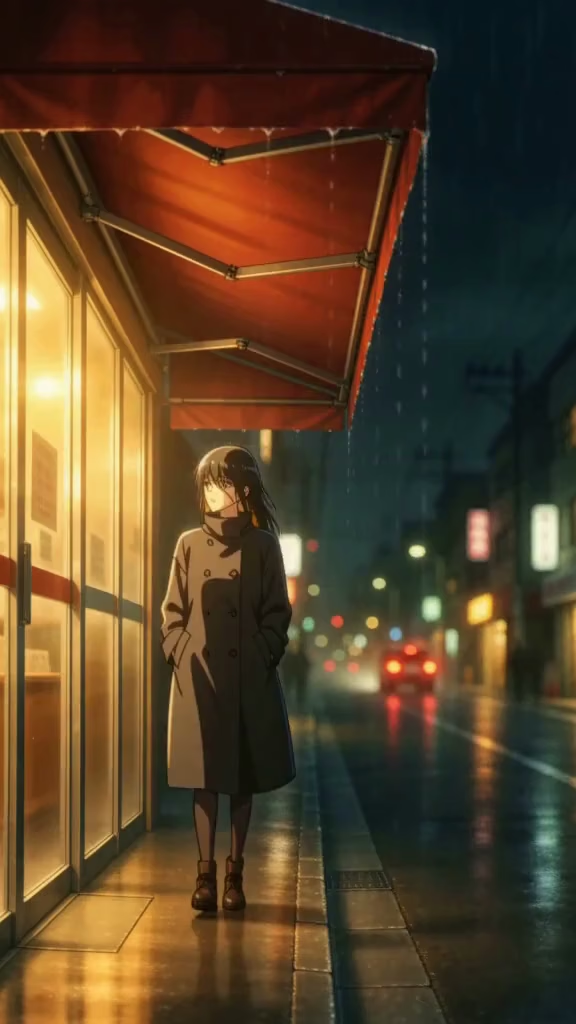
The ladder
One two-shot scene, with more reference behind it each time.
- A single face crop, and nothing else
- Plus one full-length reference: two in total
- Plus the same character dry, half and full: four in total
- Plus a scene master plate for the location the two shots share
Before class
Gather whatever reference images already exist for one character — even just a single face crop — to use as the starting point for this week’s ladder.
This week’s exercise
Build all four ladder tiers of reference material, then generate the same two-shot scene against each tier and audit both shots item by item. Bring the four reference sets, the resulting shots, and the audit notes to Wednesday’s Dailies.
Reading
LoRA: Low-Rank Adaptation of Large Language Models
Hu et al.2021
freezes the pre-trained model weights and injects trainable rank decomposition matrices into each layer
DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation
Ruiz et al.2022
Given only a few (typically 3-5) casually captured images of a specific subject
VACE: All-in-One Video Creation and Editing
Jiang et al.2025
reference-to-video generation, video-to-video editing, and masked video-to-video editing
Phantom: Subject-consistent video generation via cross-modal alignment
Liu et al.2025
extracts subject elements from reference images and generates subject-consistent videos following textual instructions
MiniMaxAI2026
Up to 9 reference images, 3 reference videos