In week 2, the double empathy problem was a theory: when two people of different implementations misunderstand each other, the misunderstanding is mutual (Milton, 2012). This week is the evidence, and what to do with it.
Where the loss happens#
Crompton and colleagues built diffusion chains of eight people. The first person heard a story and retold it to the second, who retold it to the third, and so on down the chain. Some chains were all autistic, some all non-autistic, and some mixed (Crompton, Ropar et al., 2020).
- all autistic: a chain of 8 people, each retelling the story to the next.
- all non-autistic: a chain of 8 people, each retelling the story to the next.
- mixed: both, in one chain: a chain of 8 people, each retelling the story to the next.
| Chain | Detail retained along the chain | Rapport between people |
|---|---|---|
| All autistic | no significant difference from non-autistic chains | higher than mixed |
| All non-autistic | no significant difference from autistic chains | higher than mixed |
| Mixed | declined significantly more steeply | lower |
The mixed chains lost detail faster. The all-autistic and all-non-autistic chains did not differ significantly. That challenges an account in which autistic people simply lack the ability to share information. It does not tell us which individual retelling lost which detail.
Misreading runs in both directions#
Sheppard and colleagues filmed people reacting to events, then asked non-autistic observers to work out which event each person had experienced. Observers were less accurate for autistic people. Yet autistic people were rated just as expressive for most of the events, and their reactions were described differently. Their reactions differed; they were not reduced (Sheppard et al., 2016).
DeBrabander and colleagues then asked autistic observers too. Autistic and non-autistic raters made similar trait judgements of autistic adults. The difference was what came next: for autistic raters, those judgements didn’t reduce their interest in interacting, as they did for non-autistic raters (DeBrabander et al., 2019).
So both implementations notice the difference. What varies is whether the difference counts against someone.
Why misreading turns into being liked less#
Week 2: style is judged in seconds, before content. This week: autistic people’s reactions are misread rather than missing. Could the two be linked?
Alkhaldi, Sheppard and Mitchell took the same videos Sheppard’s team had filmed and scored each target for one thing: how readable they were. Then new groups of neurotypical perceivers rated them.
The neurotypical targets were rated more favourably — and that held whether the perceivers were kept in the dark about what the person was reacting to (Study 1) or told (Study 2):
Readability correlated with favourability — r = .58 and r = .63 — independent of target diagnosis (Alkhaldi et al., 2019).
Readability and diagnosis are separate parts of the reported result. The correlation is not evidence that diagnosis had no relationship to the ratings.
The authors write that perceivers might rate people unfavourably because they find them hard to read, though other interpretations of the correlation are also possible. This is correlational.
In the room — readable to whom? (7 min)#
Three minutes, alone. Think of one person you find easy to read and one you find hard. Write one concrete thing each of them does — an actual behaviour, not an impression. The asleep test applies.
Leave out identifying details. If no example comes to mind, compare the fictional behaviours “nods after each sentence” and “waits until the speaker finishes, then gives a full reply”. Treat your interpretation as a prediction.
Three minutes, in pairs. Swap lists. Would your partner’s “easy” behaviours be easy for you?
One minute, the room. Hands up if any behaviour on your partner’s easy list was on your hard list, or the reverse.
Whatever the count is, it is a finding about this room and no other. The reason to run it is what any disagreement would show: that “hard to read” needs a second half of the sentence. Hard to read by whom.
Rapport signals are implementation-specific#
Rifai and colleagues went back to the diffusion-chain videos and coded two candidate signals of rapport: mutual gaze and backchannelling (the “mm-hm”, the nod). In mixed pairs, less of both went with lower rapport. But in autistic pairs, less backchannelling went with higher rapport (Rifai et al., 2022).
The visible signs that someone is engaged are part of an implementation, not a universal readout. A listener who never says “mm-hm” may be the most engaged person in the room, by their own implementation’s measure. A listener who says it constantly may be running a masking subroutine from week 6.
Who pays for the mismatch#
When 12 autistic adults described time with neurotypical friends and family, they talked about being in a minority, and about conforming to what the other people were used to in order to spend time with them. With autistic people, they described belonging, and being able to be themselves (Crompton, Hallett et al., 2020).
Mitchell, Sheppard and Cassidy set out how that compounds. The majority’s misreadings, and what people do because of them, push autistic people towards isolation over years. That damages their mental health, and it costs everyone else what they would have contributed (Mitchell et al., 2021).
Five minutes with a stranger#
Morrison and colleagues studied the question in an actual conversation.
125 people — 67 autistic, 58 non-autistic — were put into pairs. Both autistic, both non-autistic, or mixed. Five minutes of unstructured conversation with someone they had never met. Then both people rated the conversation and each other (Morrison et al., 2020).
Autistic adults were rated more awkward, less attractive, and less socially warm — by autistic and non-autistic partners alike.
Only the non-autistic adults’ interest in a future interaction followed that judgement.
Autistic participants trended towards preferring other autistic partners. And they reported disclosing more about themselves to autistic than to non-autistic partners.
The rating and the interest in meeting again came apart for the autistic participants in this study.
The number that matters most in this course#
How much a person opens up is not a fixed property of that person. It moved with who they were sitting opposite, in a five-minute conversation with a stranger.
You have met this claim before, from a completely different literature. Week 9: Kluger and Malloy’s reanalysis, arguing that about a third of the variance in how much someone asks questions belongs to the particular pair, not the person.
“Work on your social skills” addresses one endpoint of a two-endpoint problem. The evidence also locates variation in the link.
In the room — the pairing effect (8 min)#
Four minutes, alone. Name one thing about how you talk that you know changes depending on who you’re with. How much you say, how fast you answer, how much you check the other person’s face, whether you tell them things.
If you have no observed example, test a hypothesis instead: “Alex writes more in the shared document than Alex says on calls.” Mark it as untested.
Then write the test: how would you know if you were wrong about that? What would you have to observe?
Three minutes, in pairs. Read out only the second part — the test, not the thing. Check whether each other’s tests are runnable.
One minute. Anyone whose test needs the other person’s cooperation to run: say so, and name what you would need to agree with them.
What this week’s evidence doesn’t settle#
The qualitative work is 12 people. The diffusion chains are 72. The conversation study is 125.
The mixed chain’s seating order isn’t a detail this course checked, which is why the drawing above leaves those seats blank rather than guessing at them.
Alkhaldi et al. is correlational, and its authors said so themselves.
The claim that a mixed room with eleven weeks of shared vocabulary interoperates better than one without is not a tested finding. It is this course’s proposal; the partnership labs let you try it. Week 12 records this course’s untested models, including week 9’s depth scale as item E-3.
Interoperation, not conversion#
Conversion is when one implementation replaces itself to talk to the other. It is the default solution, and the pressure to convert falls on the minority, as week 6’s ledger and its pressure column showed. It can go the other way too: telling a colleague to “just be direct” and expecting them to rebuild their whole implementation for you.
Interoperation is when two implementations agree a shared protocol for the exchange at hand: what each side will send, what each will accept, and how either one flags a mismatch. Both sides concede something, and neither side replaces itself.
| Question | Conversion | Interoperation |
|---|---|---|
| Who changes | one side, entirely | both sides, partly |
| Scope | everywhere, indefinitely | this exchange, this relationship |
| When it breaks | silently, as a mismatch someone blames on themselves | out loud, with an agreed signal |
| What it costs | the week 6 ledger, for one person | a few clauses each |
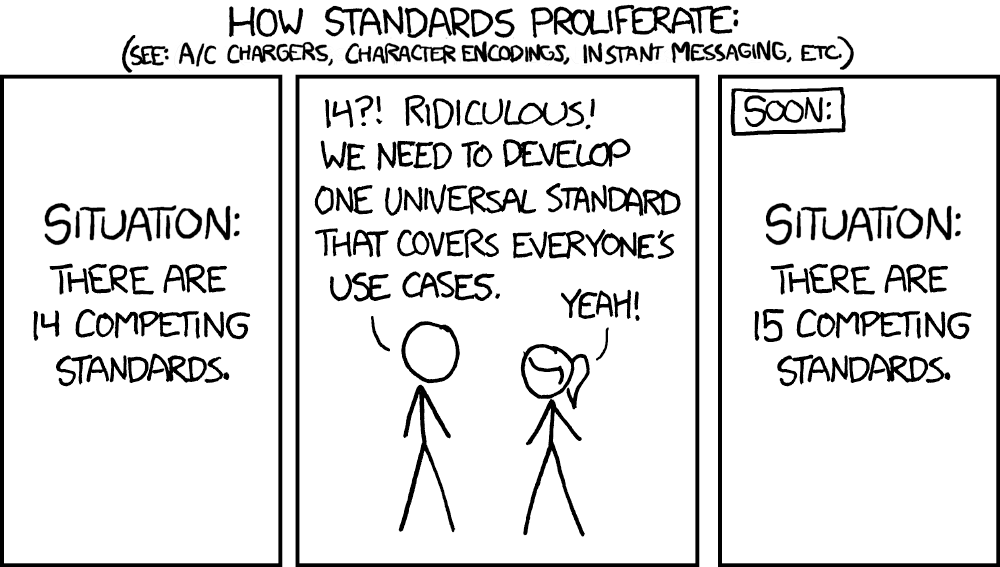
Read the comic as text
How standards proliferate (see: A/C chargers, character encodings, instant messaging, etc.). Situation: there are 14 competing standards.
Two people: “14?! Ridiculous! We need to develop one universal standard that covers everyone’s use cases.” “Yeah!”
Soon: situation: there are 15 competing standards.
The bilateral protocol#
This is the artefact at the centre of your Interoperation Report. A worked example, from two fictional lab partners. Alex backchannels constantly, hints, and answers fast. Sam answers slowly, speaks directly, and rarely says “mm-hm”.
| # | Clause | Who concedes | How either of us checks it |
|---|---|---|---|
| 1 | Sam can answer a question by message within 24 hours, rather than on the spot. | Alex: immediacy | Did any question go unanswered past a day? |
| 2 | Alex writes each request in the shared document with its action, addressee, and proposed deadline or “no deadline”. | Alex: the envelope | Does each request contain those three fields? |
| 3 | Silence on a call is not a vote. Wait for an explicit answer; either of us can say “still thinking”. | both: the timeout | Was each decision recorded only after both people answered? |
| 4 | Sam says “sounds good” out loud when agreeing, even though it feels redundant. | Sam: one token | Did Alex have to ask whether Sam agreed? |
| 5 | Either of us can say “mismatch” to flag a misunderstanding, with no explanation owed. | both | Did we use it, and did it work? |
Clause 5 is the one that makes the others safe. It turns a mismatch from something one person privately blames themselves for into a word both people agreed to say.
A question mark is not a conformance test#
These are invented messages for the worked pair:
| Request | Does it pass clause 2? |
|---|---|
| “Could the diagram be ready soon?” | No named addressee or deadline; “ready” does not say where the result goes. |
| “Sam, please upload the labelled diagram to our folder by Friday 18:00.” | Yes: an action, an addressee and a proposed deadline. It is not a question. |
| “Sam, please suggest another title in the document. No deadline.” | Yes. A deadline is not invented where none is needed. |
A check can establish that a request is explicit. It cannot establish that its deadline is feasible or agreed. That needs a reply, which clause 3 protects.
In the room — break the clause, then repair it (8 min)#
One minute, in pairs. Read the three fictional requests. Identify why checking for a question mark would pass the weakest one and reject the others.
Three minutes. Apply the three-field check. Rewrite the first request, using a proposed deadline of Friday 18:00. Each partner checks the other’s wording for information still missing.
Two minutes. New fact: Alex posts it at 17:55; Sam is at work until 20:00. The fields are present but the arrangement does not work. Revise a clause to say how deadlines become agreed and what happens when a request arrives late.
Two minutes. Each partner takes one turn using “mismatch” and proposing a new arrangement. Record what each party gives up, or the point still unresolved. Do not report this fictional rehearsal as evidence from your real partnership.
This room is the worked example#
For eleven weeks, a deliberately mixed class has been building vocabulary: payload, timeout, repair initiator, rate limit, ledger, mismatch. The words aren’t anyone’s native implementation. They’re a shared protocol, negotiated one week at a time, that lets people who run the majority protocol fluently and people who never got it handed to them talk about the same exchange in the same terms.
The glossary records that vocabulary. Your Interoperation Report asks which parts of the shared protocol held, and which you had to revise.
In the room — one clause each (9 min)#
Work with your Interoperation Report partner if present. Otherwise use Alex and Sam with a classmate and label the result a rehearsal to discuss with your partner later. Take nine minutes and get one clause written.
Three minutes. Each of you, separately: write one thing the other person does that costs you something. A behaviour, not a verdict.
Four minutes. Together, turn the two of them into a single clause with three parts: what each side will do, and how either of you checks it next week.
Two minutes. Add clause 5 — the mismatch word. Agree what yours is.
One clause is a real protocol. Draft the rest on Thursday.
What interoperation is not#
- Not meeting in the middle. The clauses aren’t symmetrical and don’t have to be. One side may concede four things and the other one, if that’s what the exchange actually needs.
- Not permanent. A bilateral protocol is scoped to a relationship and a situation. The one you write on Thursday can be renegotiated in June, and saying so out loud is what makes it safe to agree to now.
- Not a promise that it works. Every clause is a hypothesis. Clause 5 exists because some of them will be wrong, and a protocol with no way to report a fault is week 1’s problem all over again.
What this week added to the vocabulary#
Interoperation — two implementations agreeing a protocol for the exchange at hand. Conversion — one implementation replacing itself. And the bilateral protocol itself, with its mismatch clause.
Next week: the open issues, the errata, and where to read further.
If time remains#
When the costs of a shared protocol are unequal, what would make the agreement fair enough to accept and possible to renegotiate?
Optional discussion. Finish by 15:55.